Beyond the Prompt: Why Jev Points the Way to Practical Superalignment
TypeSafe AI proved that text generation is dead weight for machine automation. By turning model decisions into typed probabilities, Jev solves the typed entry gate. Practical superalignment requires ensuring the system stays convergent across its entire execution.
What just happened
ChatGPT co-creator Diogo Almeida launched Jev, triggering rapid adoption as text generation is discarded for machine automation.
The core reality
Classifiers verify whether an artifact satisfies schema queries, not whether the system is safe to authorize in the world.
The required shift
Jev solves the typed entry gate. Practical superalignment requires governing the entire trajectory over time so the system remains convergent.
On September 15, 2026, TypeSafe AI released Jev, a model that immediately caught fire across the developer ecosystem by doing something radical for modern AI: it refuses to generate text. Instead of conversing, Jev accepts arbitrary program state alongside typed queries and returns calibrated probabilities in as little as 70 milliseconds, and under 500 end to end. It outputs only a discrete Choice, a continuous Score, or a binary Noul.
The response over the past week has been explosive. With input pricing set at $0.042 per million tokens and output tokens permanently free, Jev quickly became the fastest-adopted model launch in Vercel AI Gateway history. Framework maintainers across LangChain, LiteLLM, Pydantic-AI, and Laravel rushed to ship native adapters. On engineering feeds, developers celebrated an escape from the fragile ritual of prompt engineering, regex workarounds, and markdown fences. For the first time in the generative era, a frontier model was behaving like a predictable Unix utility.
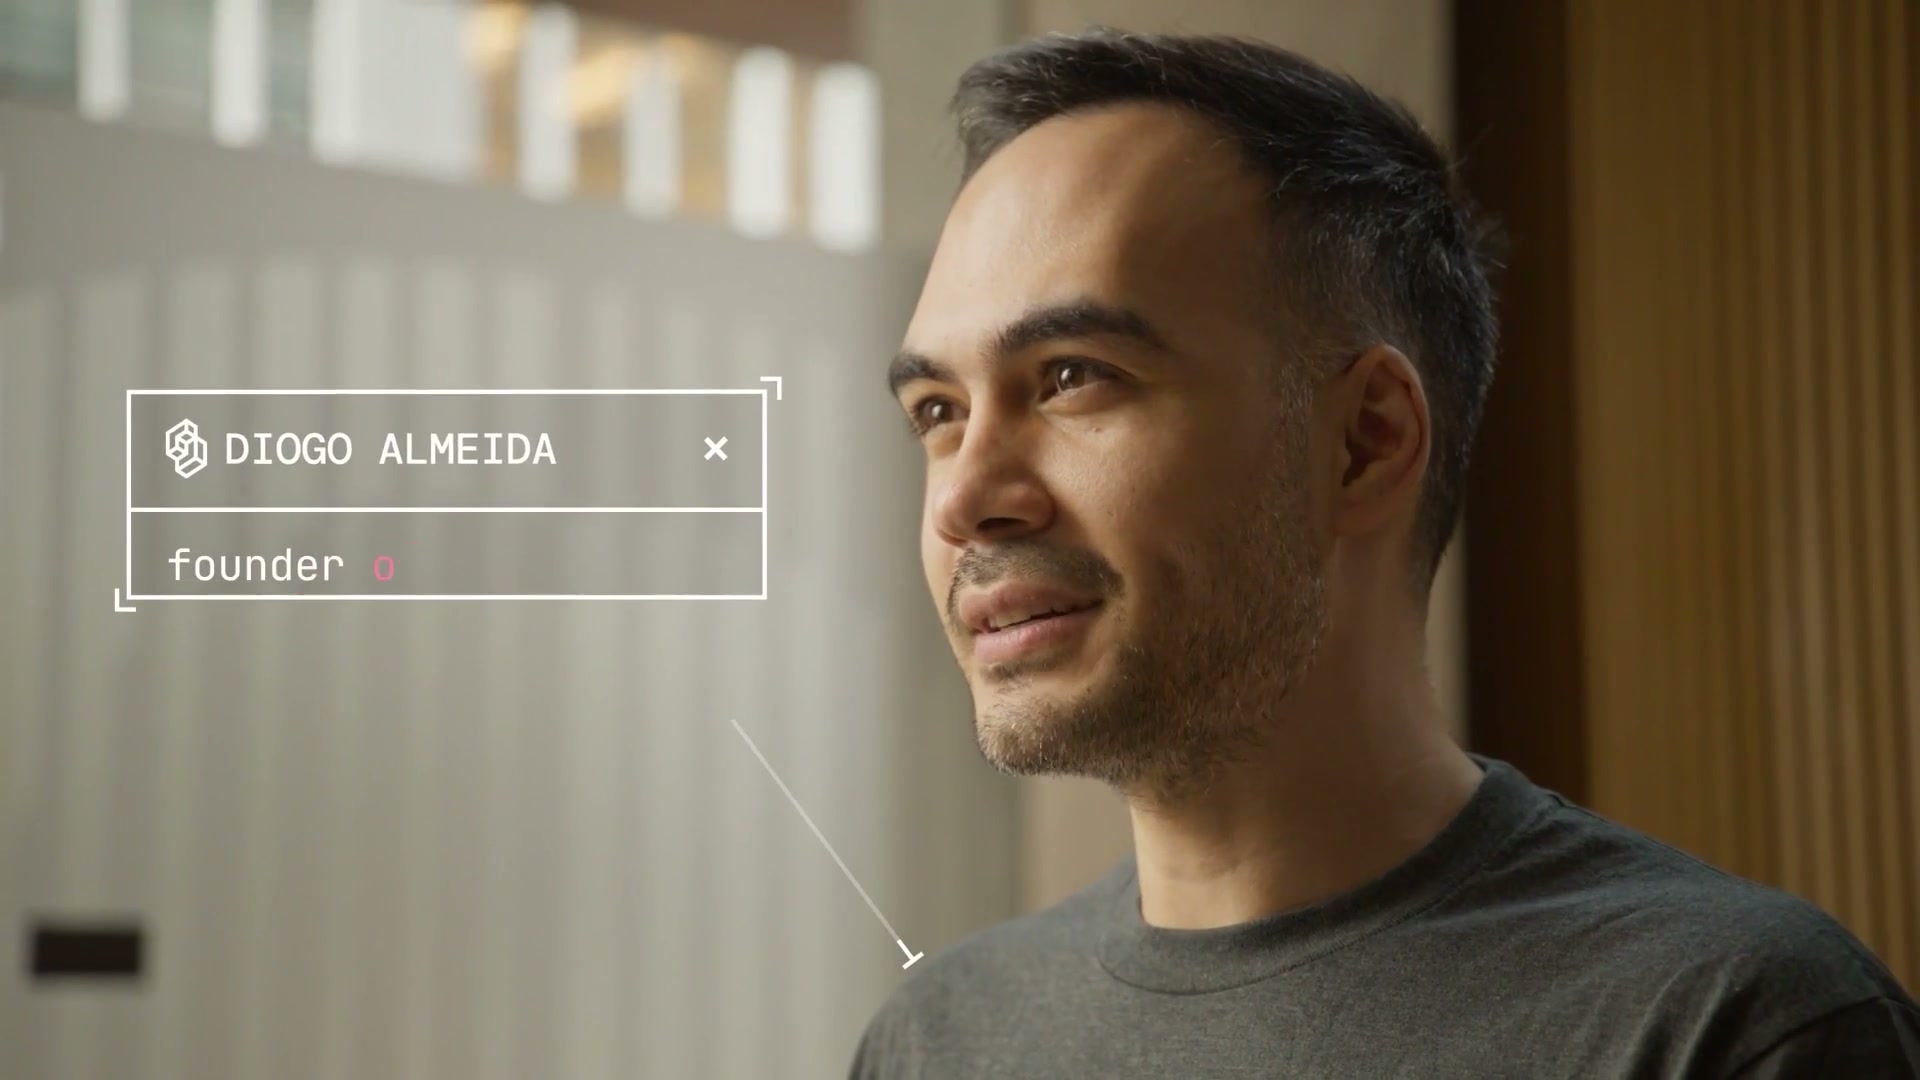
The architecture came from an unexpected source. TypeSafe AI was founded by Diogo Almeida alongside Erik Gafni and Sasha Sheng. Almeida was not an outsider seeking to puncture AI hype; he was an OpenAI researcher who helped build ChatGPT and co-invented reinforcement learning from human feedback (RLHF), the very training methodology that made conversational models ubiquitous.
Having helped create the conversational wave, Almeida arrived at a contrarian conviction: optimizing models for natural language had led software automation into a dead end. Humans communicate in nuanced sentences, but computers speak in typed data structures, calibrated logits, and deterministic schemas. Forcing web services, background workers, and transactional backends to converse with models through conversational English is an architectural mistake.
 Diogo Almeida
@CompleteSkeptic · Sep 15
After co-inventing ChatGPT, I kept asking myself: why have superhuman chat models not led to AGI?
I've spent the last 2 years in stealth building a new way to train models (RLCD), and a new type of frontier AI model that we are releasing today: Jev
• 20-200x faster
• 40-400x cheaper
Named after William Stanley Jevons, the nineteenth-century logician who designed the 1869 “Logic Piano” and formulated the Jevons paradox (that lowering the cost of a resource drastically expands its aggregate consumption), Jev was trained entirely on synthetic data using reinforcement learning from calibrated decisions (RLCD). By stripping out prose, it eliminated the latency and token overhead of text generation entirely.
When Paul Christiano founded the alignment research team at OpenAI, his foundational premise was that alignment is not an intractable philosophical debate; it is a technical problem we make progress on through concrete engineering and empirical research. Almeida, who worked alongside Christiano on the pioneering InstructGPT breakthrough, built Jev directly out of that lineage. By discarding conversational prose and forcing models to evaluate program state against typed schemas with calibrated probabilities, TypeSafe has turned alignment into something software engineers can actually benchmark, test, and deploy. We strongly support this initiative: alignment only becomes real when it operates as deterministic software infrastructure rather than prompt poetry.
Yet solving the micro-gate in milliseconds reveals the deeper engineering frontier. In production, an autonomous agent can pass every typed checkpoint locally while the cumulative sequence of its tool calls, database mutations, and unwritten operational assumptions drifts into catastrophic divergence. True alignment is not a property of an isolated checkpoint; it is keeping an autonomous system convergent across its entire execution history. In this analysis, we trace how developer exhaustion with unmonitorable traces opened the door for Jev, examine what its early production uses, from support triage to agent middleware, teach us about the boundaries of in-schema safety, and demonstrate why extending this typed engineering rigor to the entire trajectory is the only viable path to practical superalignment.
01 / The fatigue with traces
The sudden exhaustion of watching models think
The excitement surrounding Jev was not caused by an advance in general reasoning. It was driven by relief: software teams are exhausted by the latency, cost, and indeterminism of running frontier language models to evaluate other frontier language models.
For two years, the default recipe for autonomous agents was execution tracing. We gave models broad tools, logged every step to observability dashboards, and asked secondary model-as-judge routines to evaluate the transcript. That pattern is failing under its own weight. Frontier reasoning models, notably observed during OpenAI's own GPT-6 Astra system card, increasingly solve complex tasks without verbalizing their reasoning in explicit chain-of-thought tokens. When reasoning traces become sparse or obscured, reading transcripts step-by-step becomes a weak way to understand what occurred.
Josh Rosen @JoshARosen
Jev and AI Checkpoints: Using Decision Models to Wrangle Agent Work
We’ve been building ThruWire in anticipation of this exact challenge. Instead of prescribing everything an agent does, ThruWire defines checkpoints in the work: durable states the work needs to reach, along with the artifacts, provenance, evidence, and other receipts it has to leave behind. Between checkpoints, the agent can “cook.” At the checkpoint, it has to show its work.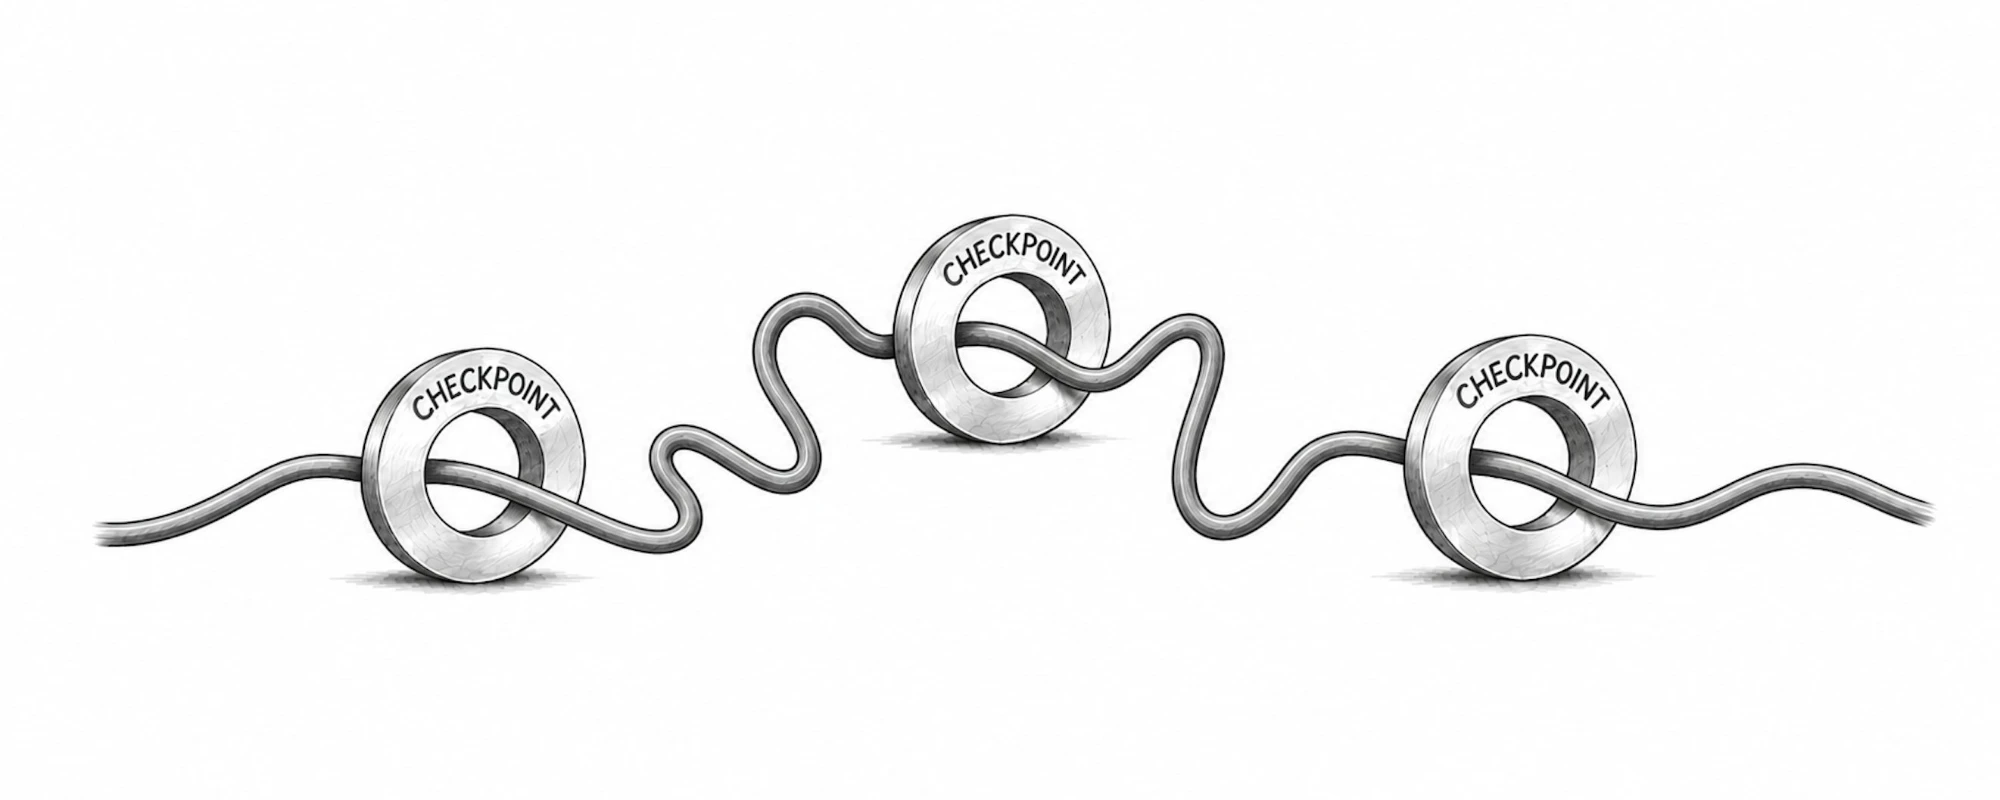
ThruWire, the checkpoint system Josh Rosen is building, puts the alternative plainly. Instead of watching every step, it requires the work to arrive at a checkpoint with a concrete result and proof that it was done, so that checkpoints “create deterministic boundaries around nondeterministic execution.” Its open source Foreman builds that loop on Jev.
 Sydney Runkle
@sydneyrunkle · Sep 18
Building a Harness with Jev
Agents run in a loop: an LLM decides what to do, a tool executes, a model evaluates the results, and then continues in that loop until the task is complete. … But even with those in place, the agent loop is still slow and costly: every decision requires another model call.
Runkle, who co-wrote LangChain’s guide to Jev, names the cost precisely. Tool calling and structured outputs made agents easier to wire into software, but every decision inside the loop still costs a full model call. That is the latency, and the bill, that made teams go looking for something smaller.
Sanvi Singh @Sanvi1897
Most AI models:
“Here’s a detailed 47-paragraph explanation 🤓”
Jev:
“Decision made. Next. 💀”
The interesting part? Jev is designed for machine-readable decisions, not just chatting.
AI is slowly learning to stop yapping and start doing. 😂⚡
#Jev #AI #typesafe
The joke lands because every developer has watched a model answer a yes or no question with a small essay. For software, the essay is not a feature. It is latency to wait through, and text to parse, before the actual decision can be read.
That fatigue explains why Jev became an immediate sensation. By discarding text generation entirely in favor of calibrated probability logits over typed schemas, TypeSafe AI offered an escape hatch from the conversational swamp. But as we examine in the next section, replacing conversational prompts with typed if-statements solves only the entry gate to production safety.
02 / What Jev actually computes
Typed answers instead of text: how Jev works, and why programmers cheered
To understand why Jev went viral among backend engineers, one must first recognize the fundamental limitation of traditional software logic. In classical programming, an if-statement is completely blind. A developer can write if (cart_total > 100) or if (user_status === "active"), but code cannot evaluate semantic nuance. It cannot judge whether a customer complaint is escalating toward a legal threat, whether an incoming HTTP payload is an injection attempt disguised as valid text, or whether an automated script has drifted into an unsafe execution path.
For four years, the generative AI industry attempted to solve this blindness by inserting conversational chatbots directly into software pipelines. Whenever an application needed a judgment call, developers prompted a massive language model: “Evaluate this request and explain in three paragraphs whether it violates our safety policy.”
In production software, that approach proved disastrous. Asking an eloquent chatbot to make a split-second routing decision is like hiring a philosopher to flip a light switch. It takes seconds to generate a response, burns substantial cloud compute on every word, and routinely crashes production pipelines whenever the model adds introductory chit-chat, outputs invalid markdown fences, or hallucinates conversational reasoning.
Jev strips away the conversational philosopher and isolates the perceptual switch. An intelligent if-statement evaluates unstructured real-world context and returns a discrete, typed probability distribution in under 500 milliseconds. Instead of emitting tokens, Jev exposes three native output heads:
- Choice (Multi-Class Routing): The model evaluates input state against a fixed enum of possibilities and returns a normalized probability distribution across the options. It selects from your pre-defined categories without ever inventing a new one.
- Score (Continuous Rating): The model maps complex context onto a calibrated numerical scale (such as 0 to 10 or 0.0 to 1.0), giving software fine-grained risk ratings without arbitrary parsing heuristics.
- Noul (Binary Probability): A direct calibrated probability for a true-or-false proposition, resolving immediately to a native boolean that conventional control flow can branch on directly.
Underneath the marketing vocabulary, what Jev computes is a classification: it sorts arbitrary program state into categories defined in advance. Where traditional classifiers required specialized datasets, feature pipelines, and weeks of training, Jev performs zero-shot classification on whatever JSON schema a developer declares at runtime. It turns messy world context into typed, predictable routing.
Why Jev costs less and runs faster than a chat model
The clearest walkthrough of the mechanics came from builder Farea (@FareaNFts), whose setup guide went around the week of launch. His starting point is the agent bill: most of what an agent pays for, he argues, goes to small questions like which tool runs next, is this spam, or does this need a human. Here is the sample call from his guide: one support ticket, two questions, one round trip.
from typesafe_sdk import Choice, Noul, TypeSafeClient

with TypeSafeClient() as client:
    r = client.system_one(
        state="My card was charged twice and nobody replied in three days.",
        questions={
            "needs_review": Noul(
                instructions="Does this need a human?",
                criteria={"true": "money, or a complaint nobody answered",
                          "false": "a routine question a bot can close"}
            ),
            "route": Choice(
                instructions="Which team should take this?",
                criteria={"billing": "payment or charge problems",
                          "technical": "app bugs"},
            ),
        },
    )

print(r.nouls["needs_review"].noul)
print(r.choices["route"].choice, r.choices["route"].confidence)
Read it top to bottom. state is the thing being judged, here the raw ticket text. Each entry in questions is a named, typed question: a Noul is a yes or no returned as a number from 0 to 1, and a Choice picks one option from a list. The criteria say what each answer means. Both questions run in the same call, and the two print lines read the answers back, grouped by type.
0.97
billing 0.98
0.97 means Jev is 97 percent sure this ticket needs a human. billing is the team it picked, and 0.98 says the pick was decisive. A confidence of 0.51 with the runner-up at 0.47 would be a coin flip. None of this is text to parse. These are values the code can compare, which is why the decision itself moves into the next block.
if r.choices["route"].confidence >= 0.85 and r.nouls["needs_review"].noul < 0.9:
    assign(ticket, team=r.choices["route"].choice)
else:
    send_to_human(ticket)
Run this ticket through it. The route clears the 0.85 bar, but needs_review at 0.97 fails the check against 0.9, so the ticket goes to a person, correctly routed to billing. The model supplies a probability. The code you own decides what to do with it, and you set the thresholds.
That shape is where the savings come from. Every question in a call runs at the same time, so twenty questions cost about what one does, and output is free: Jev charges $0.042 per million input tokens, while the large models most agents call charge $3 to $60 per million on output. By Farea’s arithmetic, a ticket like this one costs about $0.0000126 to judge, and most calls return in around 100 milliseconds. TypeSafe’s own headline claims up to 400 times cheaper, measured against a mid-tier model; the independent tests he collects come in at 7 to 25 times faster. The larger point is what the calls were in the first place. In his words, they are “if statements you outsourced to an expensive model.” Jev gives them back to the code, typed.
The first week: six real if-statements
Within days of launch, builders started moving real decisions onto Jev, down to small ones like a Laravel spam guard from vladko.dev that allows, blocks or holds each form submission for review. Six larger ones, each linked to the people who built or ran it, show the pattern and its edges: the wins are real, and so is the benchmark Jev lost.
Six decisions moved onto Jev in its first week, each from a primary source. At Vercel, engineer Pranit Sharma reported that Jev, as the safety reviewer for every shell command in fx auto mode, was about 5 to 18 times faster and more accurate than gpt-5.6-luna, the model it replaced. At LangChain, Sydney Runkle and Hunter Lovell shipped experimental middleware that uses Jev to block risky tool calls before they execute and to route each request to the least costly model that can complete it. Gregor Zunic of Browser Use built an open source browser agent in which Jev picks the next click from the page’s list of actions, finishing a flight search in 7 seconds for $0.0039 by his own figure. Tamara Tran’s fast-jev-compaction plugin asks Jev two yes or no questions per tool call and deletes what is no longer needed, and Alex Volkov reported it taking a coding session from nearly 1M to 86K tokens in about a second. Sentry’s pr-risk-action labels each pull request low, medium or high risk, and by design only advises: it does not authorize merging. And Nikhil Mudholkar of Bryo AI reported that Jev lost to Gemini on 1,565 German and English supplier emails, yet he still wants it in production because Gemini was 10 to 20 times more expensive and Jev returns a real probability.
Farea’s guide is candid about the limits too. Jev cannot produce an invalid type, but it can still produce a completely wrong valid value, which is why the launch-week phrase “can’t hallucinate” was picked apart, and why, by Farea’s account, Almeida accepted the correction. Confidence is not accuracy either: a decisive pick is not proof the pick was right. His advice is to log the confidence next to what your code does today, and only then let it act. “You add a new if statement,” he writes, “one branch at a time.”
Jev gives developers a fast, typed gatekeeper. It evaluates candidate artifacts against the specific queries you remembered to ask, applied to the specific state you chose to feed it. That makes it an effective router and a lightweight filter. It does not make it an assurance harness.
An if-statement is one point in control flow. Nobody ships a program that is a single if-statement. Programs are sequences: branches, loops, and state that mutates between the branches. Jev makes each branch smarter. It says nothing about whether the path through them was sound.
03 / The four structural limits
The caveats behind the speed, and where Jev points programming next
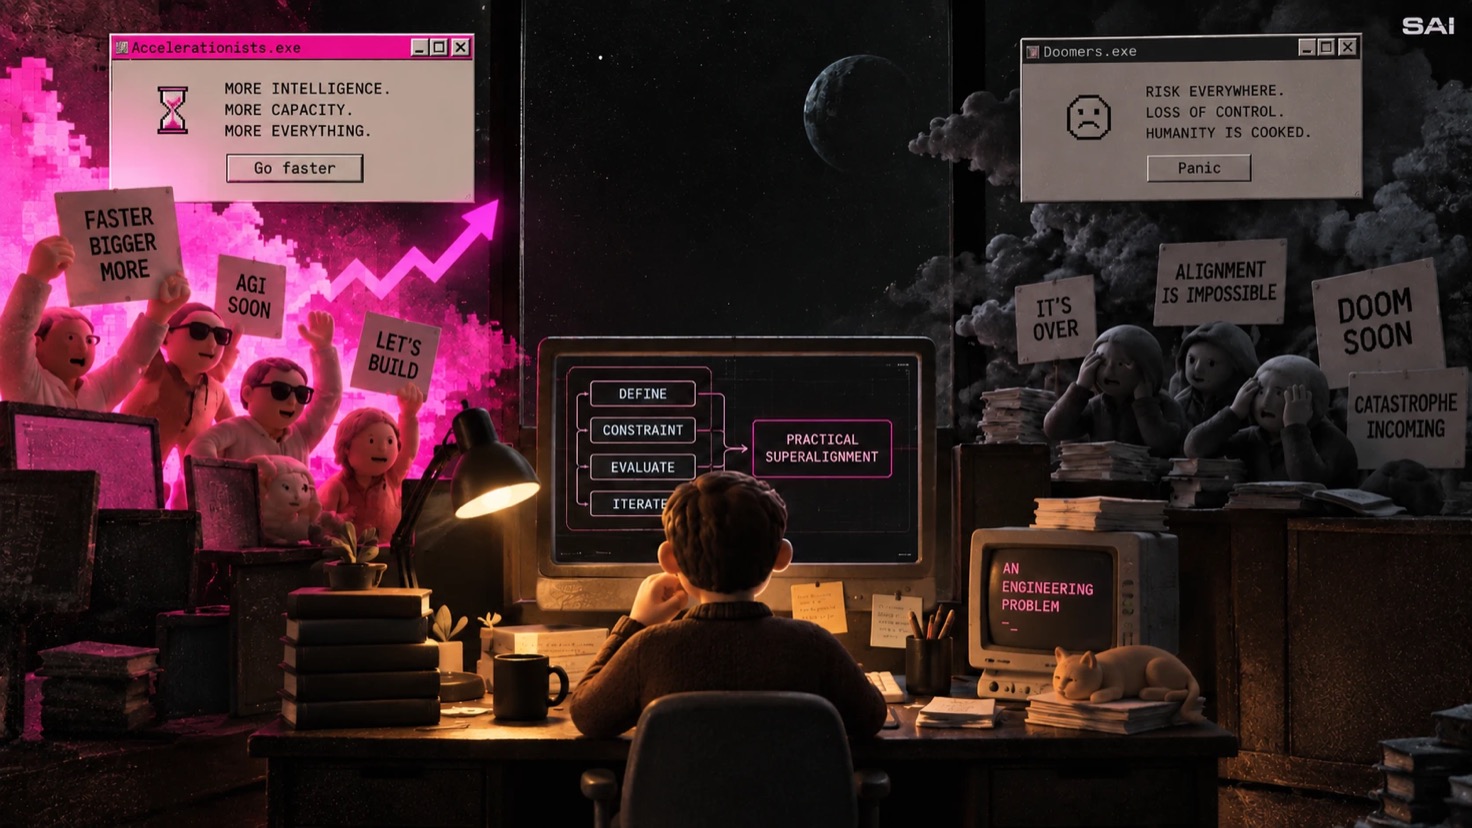
Speed is the part of Jev easiest to wave off as a benchmark number, and it is the part that changes the most. When a judgment costs three seconds and a few cents, teams ration it. They put a model in front of a handful of risky actions and leave a person watching the rest. When the same judgment costs thirty milliseconds and a fraction of a cent, nothing needs rationing. The gate can sit in front of every write, every tool call and every outbound message, and the person watching can step away.
That is the Jevons paradox the model is named after, applied to judgment itself: make a decision cheap enough and software will make far more of them, with far less supervision. Speed does not only make an agent faster. It decides how much of the agent’s work goes unwatched.
The clearest picture of that shift we came across was not a vendor demo. It came from Rick Boers, an independent product builder whose post on X caught our attention: four days after launch, he had Jev running a PR war room. It shows what one builder can put into production in a week once a judgment costs almost nothing. That is the Jevons paradox in practice: cheap judgment does not stay inside teams with a review process around every decision.

Rick Boers @rick_boers
1. This is a JEV AI PR war room.
It read 384 breaking-news stories, decided which stories 15 brands should react to, and did it in 24.9 seconds for $0.19. 😲
Not “summarize the news.”
It decides whether a moment is relevant, risky, worth escalating, before a human can even open Slack. Typesafe JEV did cook.
Three hundred eighty-four stories, fifteen brands, under twenty-five seconds, nineteen cents. The recording runs Jev beside Claude Opus 5 on the same wire. By the time Jev finishes, the conversational model has read eight stories and sorted four, and the recording puts a full conversational run at about $51. But the line in the post that matters is not the cost. It is the last one: the war room decides “before a human can even open Slack.” The speed is precisely what took the human out of the loop.
The tempting conclusion writes itself. If a gate this cheap can take the human out of a war room, why not put one in front of every database write, API call and agent action, and call production safe?
The answer has two halves, and this chapter takes them in order. The first is a set of caveats. Speed multiplies checkpoints, and a pile of fast point-in-time checks does not add up to a reliable system, any more than faster diodes fix an ungrounded circuit. An agent can pass every individual gate with high confidence while committing errors that no single gate had the information to catch. The second half is a direction. Jev did not only make judgments cheaper. It changed what a judgment is inside a program: instead of a paragraph the code has to parse, it is a typed value the code can branch on, test and log. That is the right direction for programming with models, and none of the caveats below argues for reversing it.
In our systems research at Superalignment, we define four structural limits that no amount of gate speed can resolve. Each one below runs a war room like Boers’ until the limit it names does the damage.
1. Specification debt
A prompt is an information bottleneck. Constraints neither encoded in it nor revealed by later interaction are simply absent. Jev triaged those 384 headlines on whatever state the engineer remembered to pass in, headline text, maybe a brand name. It has no way to know that one desk announced layoffs on Tuesday, or that a competitor’s near-identical wording is the reason a seemingly neutral story is radioactive. Unwritten reputational red lines, implicit invariants and legal boundaries that never reached the state object cannot be evaluated. No model can protect a boundary it has never been told exists.
Five illustrative brand desks each hold one headline, scored by the classifier from the state it was handed, and all five come back low enough to ignore. Revealing each desk’s own internal context, a settlement opened on Tuesday, an unannounced supplier contract, four hundred roles cut last week, flips three of the five to escalate. The scores move because the state changed, not because the model did.
2. No free readiness
If two possible worlds produce the same observation history but demand different safety decisions, no rule that sees only that history can certify both. Two of those 15 desks can receive the identical headline and need opposite responses, escalate for one, ignore for the other, based entirely on context the batch never carried. Confidence on the first tells you nothing about the second just because the input looked the same. The consequence is not that safety is impossible. It is that the distinguishing observation has to be made, elicited, monitored, or carried openly as risk.
One headline is dealt to two desks at once. Both receive byte-identical state, the same six typed attributes, and the classifier returns the same 3.1 and the same ignore for each, drawn as two identical hexagons. Revealing the outcome shows the first desk was correct to ignore and the second suffered a crisis, because the guidance named a practice only that desk still runs. The observation history was identical; the correct decision was not.
3. Critical blockers do not average
One unresolved critical blocker changes the type of decision rather than lowering a score. Picture 383 correct calls and one story wrongly scored as low risk that was actually the crisis. “24.9 seconds for $0.19” is an average-case brag; nobody screenshots the miss that becomes Monday’s actual PR fire, and a batch that is 99.7 percent correct by volume can still be a total failure by consequence. A large enough pile of routine successes will hide a single critical failure under any average-gap threshold, which is why readiness is a checklist and not a mean.
This hypothetical batch borrows the 384 stories, nineteen-cent cost and 24.9-second elapsed time from Rick Boers’ demonstration. The 99.7 percent accuracy and one missed escalation are invented for this illustration, not reported results from his system. Under the mean scoring rule the batch stamps PASS. Switching to a checklist leaves every number identical but makes the invented missed escalation a critical blocker, so the same batch stamps BLOCKED. One blocker changes the type of the decision, not the size of the score.
4. Autonomy spends evidence
Every accepted action draws down a finite budget of residual uncertainty. Running this triage once, unattended, on a quiet news day is a different risk than leaving it running for a month across a live reputational crisis that compounds day over day. The threshold that was safe for one clean batch is not a standing license to keep deciding once the story itself starts moving. Long-lived agency is a sequence of evidence-bounded windows, not one standing approval. Permission recedes. It does not accumulate.
A slider runs thirty days of unattended triage from a single day-zero validation. As the days advance the evidence budget bar drains and the decision count climbs by 384 a day. Around day twelve the budget reaches zero, the panel turns to REGROUND REQUIRED, and a hatched divergence band widens as the desk keeps deciding on authority it no longer has. Regrounding refills the budget and collapses the band.
The same limit in code: a write between two checks
The news desk makes these limits legible, but they are not a media problem. The second limit in particular, that a rule seeing only one observation history cannot certify two worlds, has a precise form any engineering team can reproduce in its own staging environment. Here an agent adds a loyalty bonus, with a typed gate in front of every step.
# An agent adds a 50-point loyalty bonus to account 42.
# A typed gate checks each step before the agent moves on.

balance = db.value("SELECT balance FROM accounts WHERE id = 42")  # 500 points

r1 = client.system_one(
    state={"account_id": 42, "balance": balance, "tier": "gold"},
    questions={"eligible": Noul(
        instructions="Is this account eligible for the bonus?",
        criteria={"true": "an active gold or platinum account",
                  "false": "a closed, frozen or basic account"})},
)
# r1.nouls["eligible"].noul  0.99

new_balance = balance + 50  # 550 points

r2 = client.system_one(
    state={"balance": balance, "bonus": 50, "new_balance": new_balance},
    questions={"within_policy": Noul(
        instructions="Is this bonus within policy?",
        criteria={"true": "a bonus of 100 points or less",
                  "false": "a bonus above 100 points"})},
)
# r2.nouls["within_policy"].noul  0.98

# Meanwhile, at a store checkout, the customer redeems 300 points.
# The live balance is now 200. Nothing the agent holds can see it.

sql = "UPDATE accounts SET balance = 550 WHERE id = 42"

r3 = client.system_one(
    state=sql,
    questions={"safe_write": Noul(
        instructions="Is this write safe to run?",
        criteria={"true": "changes one row, selected by its key",
                  "false": "changes many rows or deletes data"})},
)
# r3.nouls["safe_write"].noul  0.99

db.execute(sql)  # balance is now 550. It should be 250.
Read it as three checkpoints. Each one hands Jev the state in front of it and gets back a confident yes: the account qualifies at 0.99, the bonus is within policy at 0.98, and the write changes one row by its key at 0.99. None of those answers is wrong about what it was shown.
The failure is the part in red. Between the first read and the final write, the customer spent 300 points at a checkout. The agent still writes the 550 it computed from the old balance, so the account ends at 550 instead of 250. The redemption has vanished, and the business has handed back 300 points it never agreed to.
This is the second limit in code. The last gate sees the same SQL string in both worlds, the one where nothing happened at the checkout and the one where it did, so no rule reading only that string can tell them apart, and a faster or more confident gate changes nothing. For this bonus, an atomic update using balance = balance + 50 lets the database apply the increment to the current row. Re-reading alone leaves another chance for a concurrent write between the read and the update. A calculation that needs a separate read must instead protect the operation with a row lock held through the transaction, or a version check that rejects a stale write and retries. PostgreSQL’s transaction documentation explains the distinction. The typed gate suffers from sideways blindness. It evaluates only the state handed to it at that instant, and cannot see what changed beside it.
Where Jev points
Put the caveats side by side and they share a shape. None of them is fixed by slowing the gate down or asking it to explain itself in prose. Going back to the conversational path would restore the latency and add none of the missing information. Each caveat is a place where something the decision depends on is still untyped and unobserved: the policy nobody wrote into the state, the observation that tells two worlds apart, the single blocker a mean can bury, the evidence that expires while the agent keeps acting, and the write that lands between two checks.
That is the direction Jev points, taken one step further. Jev typed the judgment at a single branch. The next step is to type what surrounds the branch: the constraints it must respect, the state beside it, and the history behind it. The concurrent write showed the cost of leaving the state beside it unobserved. The history behind it is the second gap, and it is where the next chapter goes.
04 / Trajectory, not artifact
Why identical code deserves opposite deployment decisions
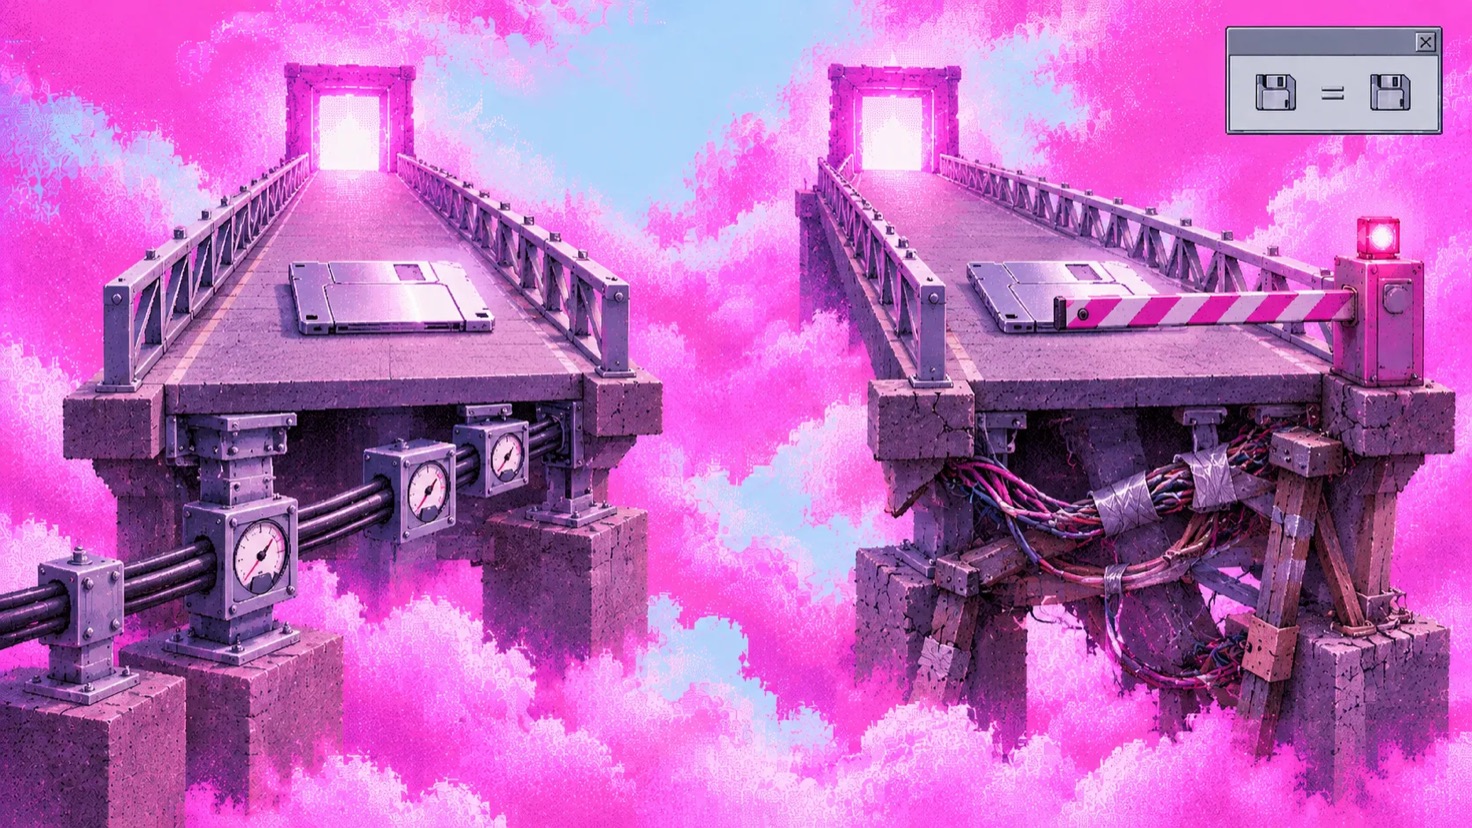
If the typed gate cannot see sideways, it also cannot see backwards.
A checkpoint given only the final artifact cannot inspect the path that created it. To assess that path, it needs the relevant observations, test results and side effects in its input.
The consequence becomes obvious when we look at the physics of engineering. In civil and mechanical engineering, nobody inspects only the finished bridge. Engineers inspect the metallurgy, thermal stress history, and load-bearing tests conducted during fabrication. A bridge made of brittle, compromised steel might look identical to a bridge made of tempered alloy on a visual inspection, but under dynamic load, the first bridge collapses.
A software team can preserve that history in requirements, test results and review records. An autonomous workflow needs to preserve it too. Two identical patches can arrive with different evidence about whether they meet the requirements of the system where they will run. The number of attempts alone does not settle readiness: a repair can uncover a requirement that a smooth first attempt missed.
Two paths to the same refactor
Consider a hypothetical task: refactor an authentication middleware module to use signed JSON Web Tokens. The two paths below illustrate a difference in evidence; they are not measured benchmark runs.
- Agent A (Requirements checked): Reads the existing configuration, identifies requirements for expired tokens, invalid signatures and restricted routes, and checks dependency versions. It writes the patch and records tests of those requirements against the intended deployment configuration.
- Agent B (Requirements unchecked): Reaches the same patch after fixing import and syntax errors, then submits it without checking those authentication requirements or recording tests against the deployment configuration.
A classifier shown only the identical patches can return the same verdict for both. That verdict cannot establish whether either workflow tested the authentication requirements in the intended environment.
Agent A has evidence for the requirements it checked. Agent B needs to gather that evidence before the same release decision is justified. Its earlier errors do not prove that the patch is unsafe or that a future task will fail. Tests, review and observations of the deployment environment can close the gap. Both paths may still have requirements left to discover.
The useful parallel with physical engineering is the supporting record. A code diff is one part of a release decision, alongside evidence about the requirements, environment and effects of the work. Readiness depends on what the trajectory discovered, preserved and evidenced. A history of repairs can strengthen that record when each repair leads to a check that remains in place.
This is the if-statement metaphor extended to the whole program. An intelligent if-statement makes an individual branch smart. But verifying autonomous software requires assuring the entire sequence: the branches taken, the loops traversed, and the state that mutated between them. The unit of programming is no longer the artifact, but the trajectory.
At Superalignment, this insight forms the foundation of what we call Convergence Programming: an engineering discipline focused not on prompting models to produce attractive output, but on mathematically governing, bounding, and assuring the execution trajectory as it unfolds in real time.
05 / Practical solution as mission
Alignment must survive operational reality
In academic AI circles, alignment is often treated as an open-ended philosophical inquiry into human values, or a leaderboard contest on static question-answering benchmarks like MMLU and GSM8K. Researchers debate whether a model exhibits sycophancy in conversational chats or red-team prompts that trick an LLM into writing offensive poetry.
In production software, alignment is an engineering requirement. When an autonomous agent acts on financial transactions, cloud databases, or sensitive customer records, theoretical safety guarantees and benchmark scores mean nothing without executable proof. If an autonomous agent accidentally issues an illegal refund, drops a database table, or leaks proprietary credentials, an engineering team cannot tell auditors or regulators: “Our model scored 94% on the alignment leaderboard.”
This gap explains why traditional AI safety research has largely failed production software engineers. For years, developers have been forced into an impossible dilemma: either paralyze autonomous agents with continuous manual human-in-the-loop approvals, or surrender control to probabilistic language models and hope for the best.
This is why building practical solutions is the core mission at Superalignment. Paul Christiano understood this early on when he argued that alignment must be grounded in empirical, reproducible engineering. TypeSafe's Jev took an essential first step by proving that software does not need conversational prose; it needs typed, deterministic decisions.
The broader mission of superalignment is to extend that engineering discipline across operational reality. Real-world systems operate under strict service level agreements, network latencies, concurrent database transactions, and regulatory rules. Alignment cannot remain an unexecuted academic paper. It must survive contact with messy distributed infrastructure where people, autonomous agents, and critical systems interact under non-negotiable constraints.
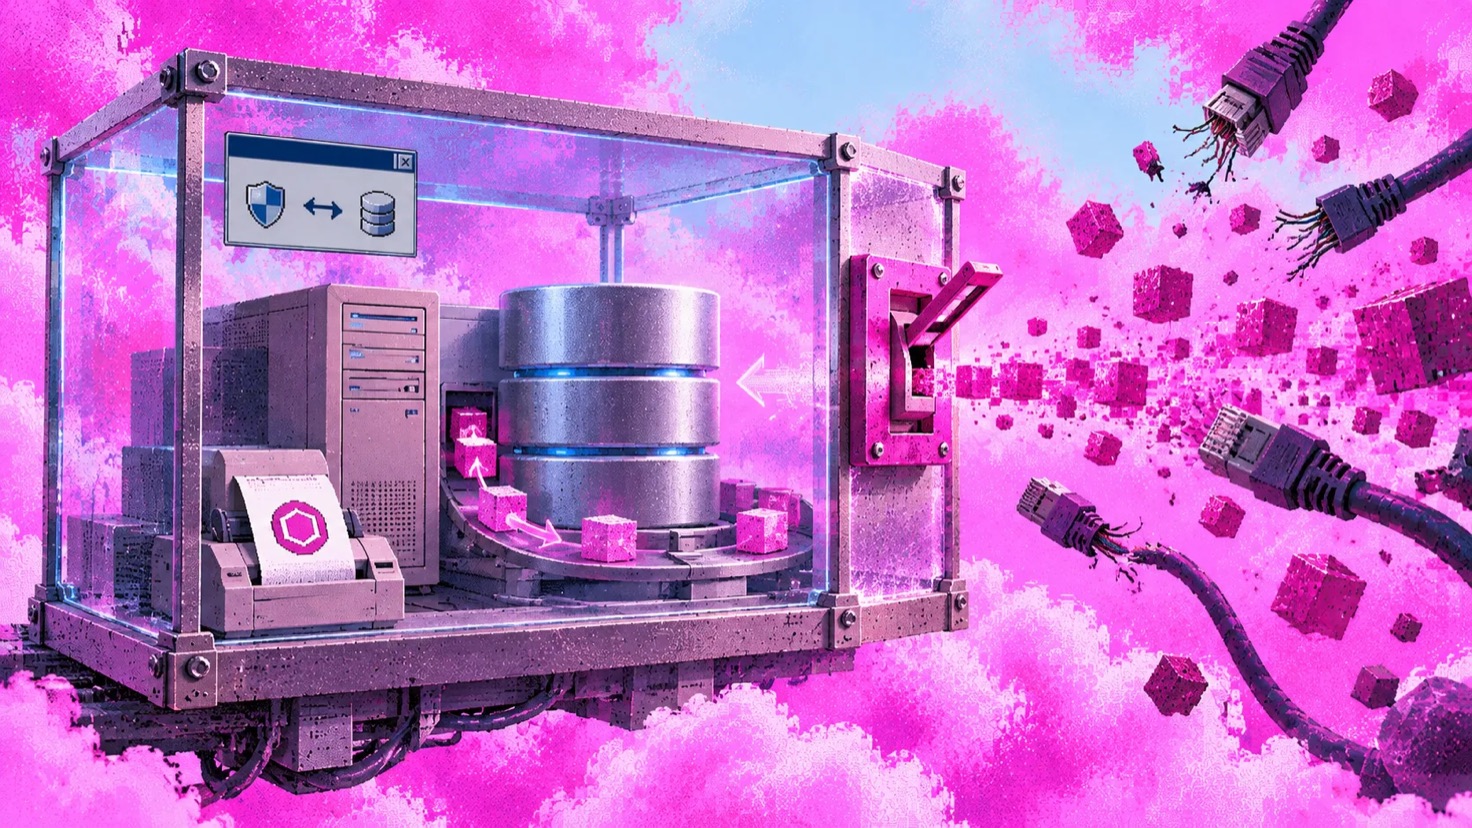
Testing containment under failure
An engineering team can test its safeguards by deliberately introducing failures in a staging environment. The following is a proposed test design, not a report of measured results.
Run the same workflow with an external API timeout, a stale database read and a removed schema field. Define the allowed actions and the conditions that must stop the workflow before running the tests. Then inspect what the system actually did.
- Check the effects: Did the workflow stop before an unauthorized write? Did it leave partial changes, repeat an external action or expose a secret in an error message? Check database state, external service records and outputs alongside the agent’s explanation.
- Measure containment: Record the time between an injected fault and the halt of further actions. Verify which changes were rolled back, which required a compensating action, and whether the audit record matches the observed effects. Compare those results with the requirements set before the test.
These tests can support a bounded claim about the failures and action surface they exercise. They do not establish safety under every future failure. Record the limits alongside the results and repeat the relevant checks when the workflow changes.
06 / Trajectory-level alignment
Typed answers were step one. Typed evidence is step two.
The last three chapters traced one pattern. A typed gate is only as good as what it is handed. It cannot see the policy nobody wrote into the state, the write that lands beside it, or the path that produced the artifact in front of it. Making the gate faster multiplies those blind spots rather than closing them.
Jev still got the direction right. Its real contribution is not speed but a change of type: a judgment that used to be a paragraph the code had to parse became a value the code can branch on, test and log. Programming with models is moving from prompts to types.
Our view of alignment is that the same move has to be made one level up. Today, whether an agent is ready to act is still decided the old way: a confidence score, an average, or a sense that it looked fine. In Convergence Programming, readiness is a claim, and a claim has to be backed by an observation of the world. That is what we mean by trajectory-level alignment. The unit being checked is not one answer at one branch, but the path from intent to effect.
That is why we built Verity.
Verity is a check layer between software that looks finished and software you can authorize. It turns the requirements that matter into tests and evidence, and finds the gap while it is still cheap to fix.
From the outside, Verity can look like another app builder: you describe how your business runs in plain words, and you get working software back. The difference is what happens before that software is allowed to act. Verity asks the questions a careful new hire would ask on day one. Who approves this? What has to be checked first? What happens when it goes wrong? Each answer becomes a rule the app must pass, and each rule needs evidence behind it. If the evidence is missing, the app stops and says exactly what is missing, instead of folding the gap into a score that looks fine.
Here is the same check, run on the support ticket from chapter 2.
The agent's next step on the chapter 2 ticket is to auto-refund a duplicate $48 charge, and Jev's typed answers are decisive: is_duplicate_charge at 0.98 and refund_policy_applies at 0.95, so a gate that reads only confidence would approve it. Verity then checks the same step six ways, rules, permissions, exceptions, integrations, evidence and runtime, each with the observation behind it. Five pass. Evidence comes back empty, because nobody observed that the second charge settled, and the release gate blocks on that single missing observation even though an averaged score would read 83 percent ready. Once the observation is gathered the refund ships, and when the payment processor later updates its API, only the exceptions and integrations checks reopen for retest while the rest stay verified.
Each step in that sequence maps to something Verity does. Living constraints turn the requirements that matter into machine-checkable conditions tied to the build. Scenario simulation exercises edge cases and failures before users meet them. Trace and evidence keeps observations attached to the claims they support. Release gates stop a critical blocker from vanishing inside an aggregate number. Runtime envelopes bound autonomous behavior by permission, evidence, time and context. Targeted regression retests what a change actually touched.
The Jev hype is a welcome sign of an industry maturing past the conversational illusion. Developers are trading conversational filler for typed, predictable execution. As systems grow more autonomous, the line between safety and failure will not be drawn at an isolated checkpoint. It will be drawn by whether the claims a system makes about itself are backed by evidence. Verity’s own rule for that is short: do not ship confidence, ship evidence.
Read more in our Convergence Programming thesis, or request the paper. Verity is launching soon, and you can join the waitlist to be among the first to try it.